ROBOTREPLICA / SITE 01 / SO-101
VLA-Replica
A Low-Cost, Reproducible Benchmark for Real-World Evaluation of Vision-Language-Action Models
SITE MAINTAINERS
Intelligent Robotics and Vision Lab at the University of Texas at Dallas
01 / ABSTRACT
Abstract
Vision-Language-Action (VLA) models have shown strong promise for general-purpose robotic manipulation, but their real-world evaluation remains limited by a lack of accessible, reproducible, and consistent benchmarks. Simulation benchmarks fail to capture real-world complexity, while existing real-world benchmarks often require expensive hardware, centralized evaluation, or are limited in task diversity.
We introduce VLA-Replica, a low-cost, easily reproducible real-world benchmark for evaluating VLA models. Built from off-the-shelf components, the system can be quickly assembled and replicated across laboratories, providing a consistent environment for policy evaluation anywhere in the world. It includes diverse manipulation tasks, a small-scale demonstration dataset for target-domain adaptation, and protocols for both in-distribution and out-of-distribution evaluation. Results across independently constructed setups demonstrate the reproducibility of the benchmark.
02 / OVERVIEW
Overview
One standardized platform, ten manipulation tasks, and a complete train-to-evaluation workflow.
03 / BUILDING THE PLATFORM
Building the Platform
A user with no prior knowledge of the benchmark assembled the setup within one hour using the published guide.
Replicate the physical setup
- Source the SO-101, cameras, enclosure, lighting, and task objects.
- Assemble the workspace and fixed camera mounts.
- Calibrate the robot and cameras using the documented procedure.
- Verify the platform against the reference scenes.
04 / CAMERA CALIBRATION
Calibrate consistent camera views
We use an AprilTag to guide camera placement and overlay reference images on the live camera feeds to calibrate the top and wrist cameras.
This helps maintain consistent camera viewpoints across replicated setups.
AprilTag guidanceLive reference overlayTop + wrist cameras
05 / MANIPULATION TASKS
Manipulation Tasks
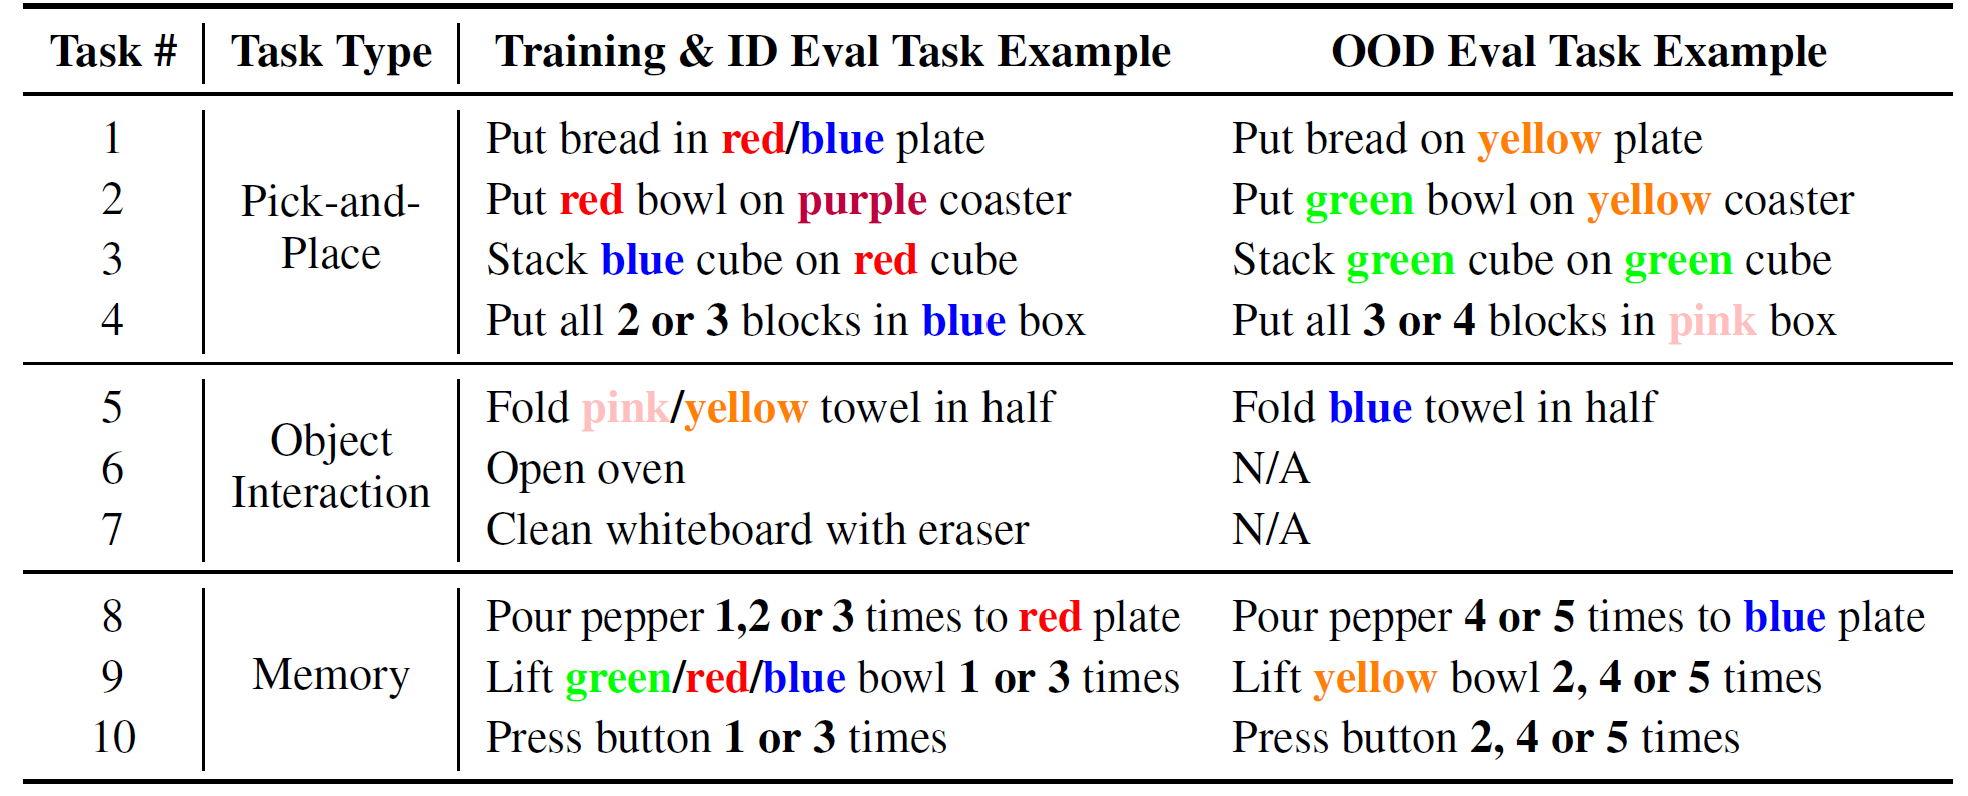
Ten tasks test physical skill, object interaction, and instruction following across training, in-distribution, and out-of-distribution conditions.
Open detailed task referencePick-and-Place
Place bread and bowls, stack blocks, and collect multiple objects.
Object Interaction
Fold a towel, open an oven, and erase a whiteboard.
Counting & Memory
Shake pepper, lift a bowl, and press a button a specified number of times.
06 / EXPERT DEMONSTRATIONS
Expert Demonstrations
We provide 50 demonstrations for each task for training or fine-tuning.
Download demonstration data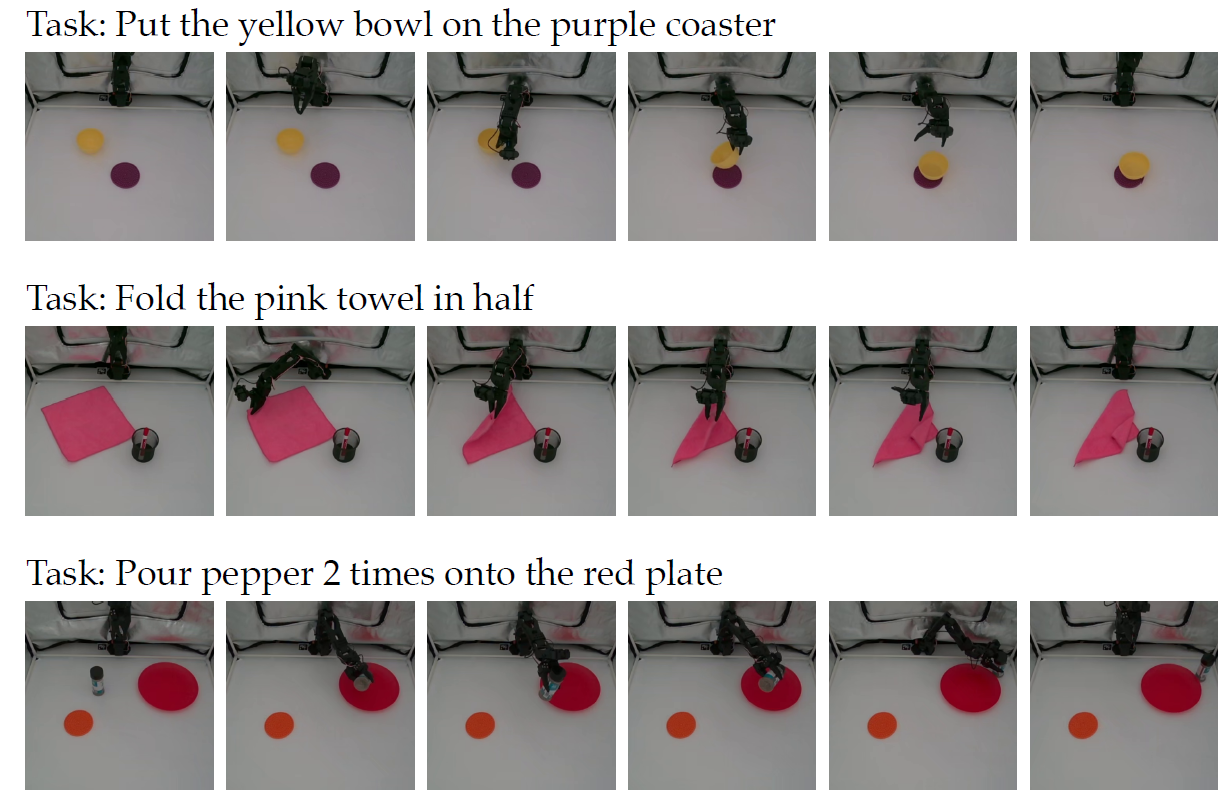
07 / TEST SCENES
Test Scene Reference Images
PLACEMENT GUIDE
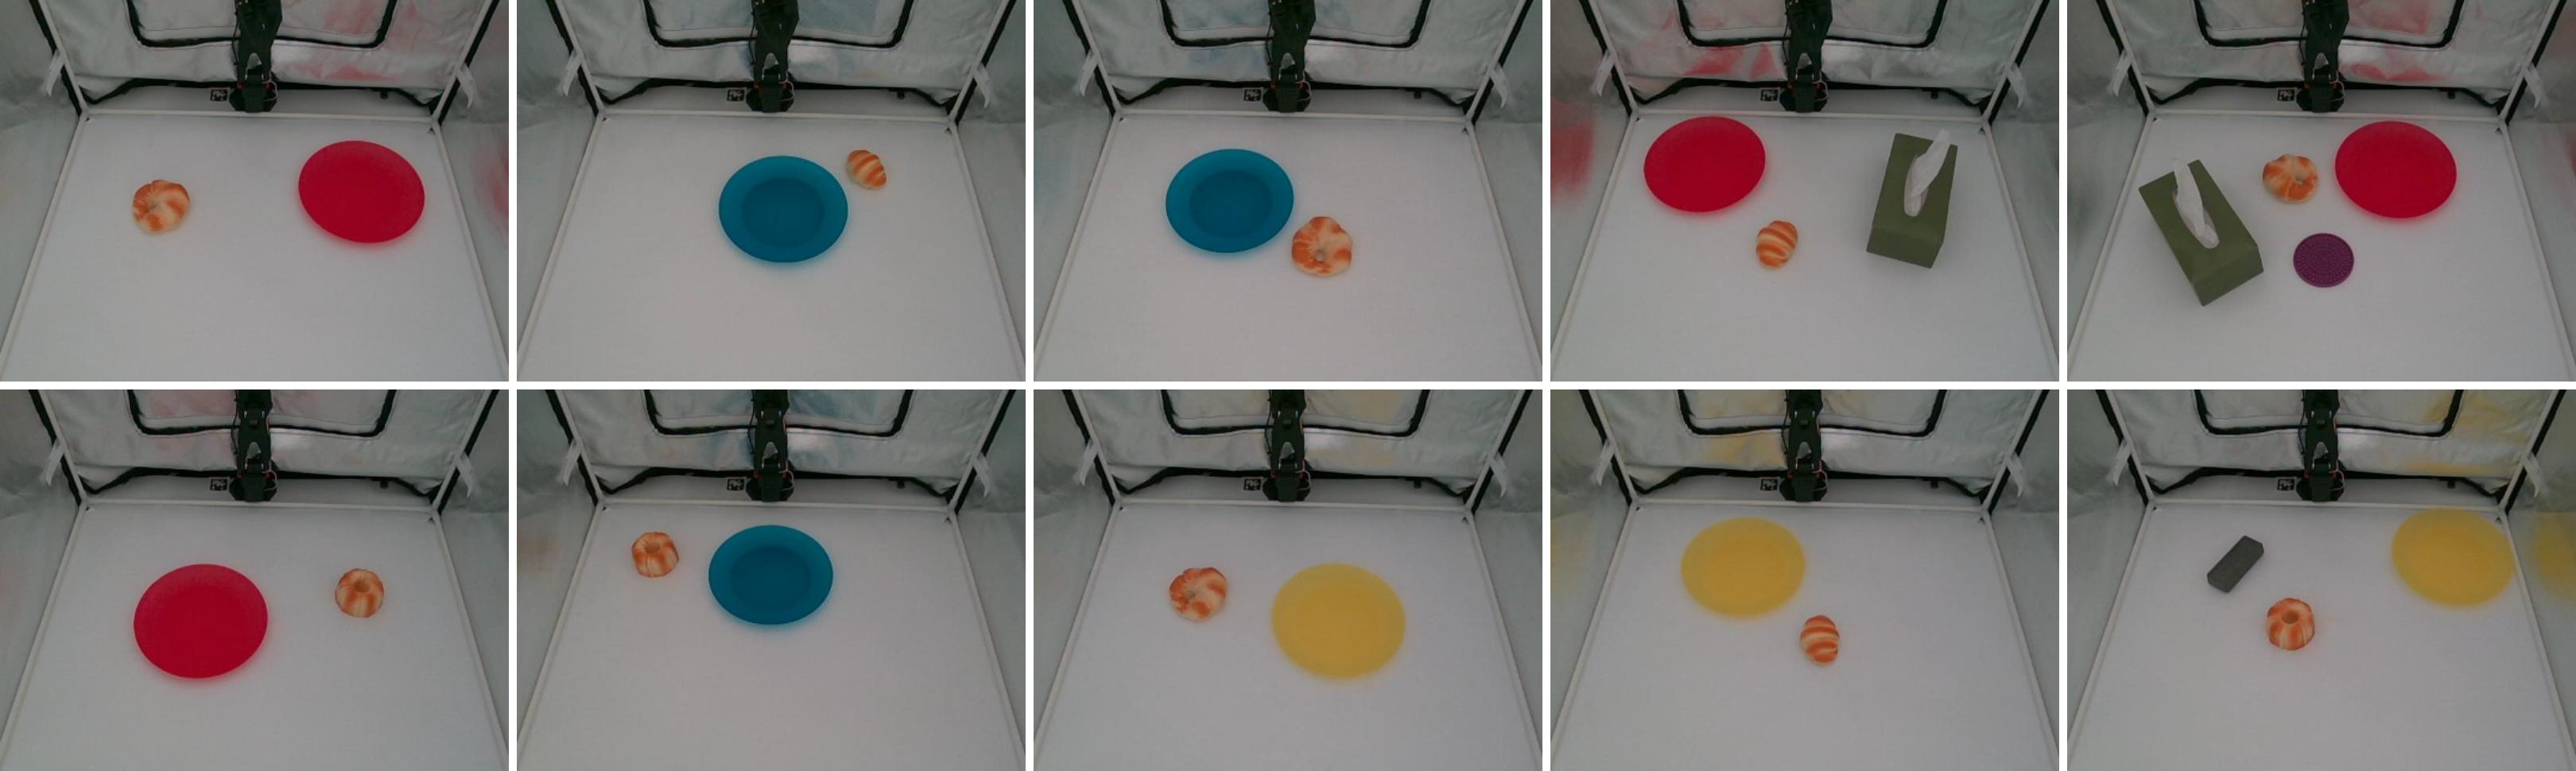
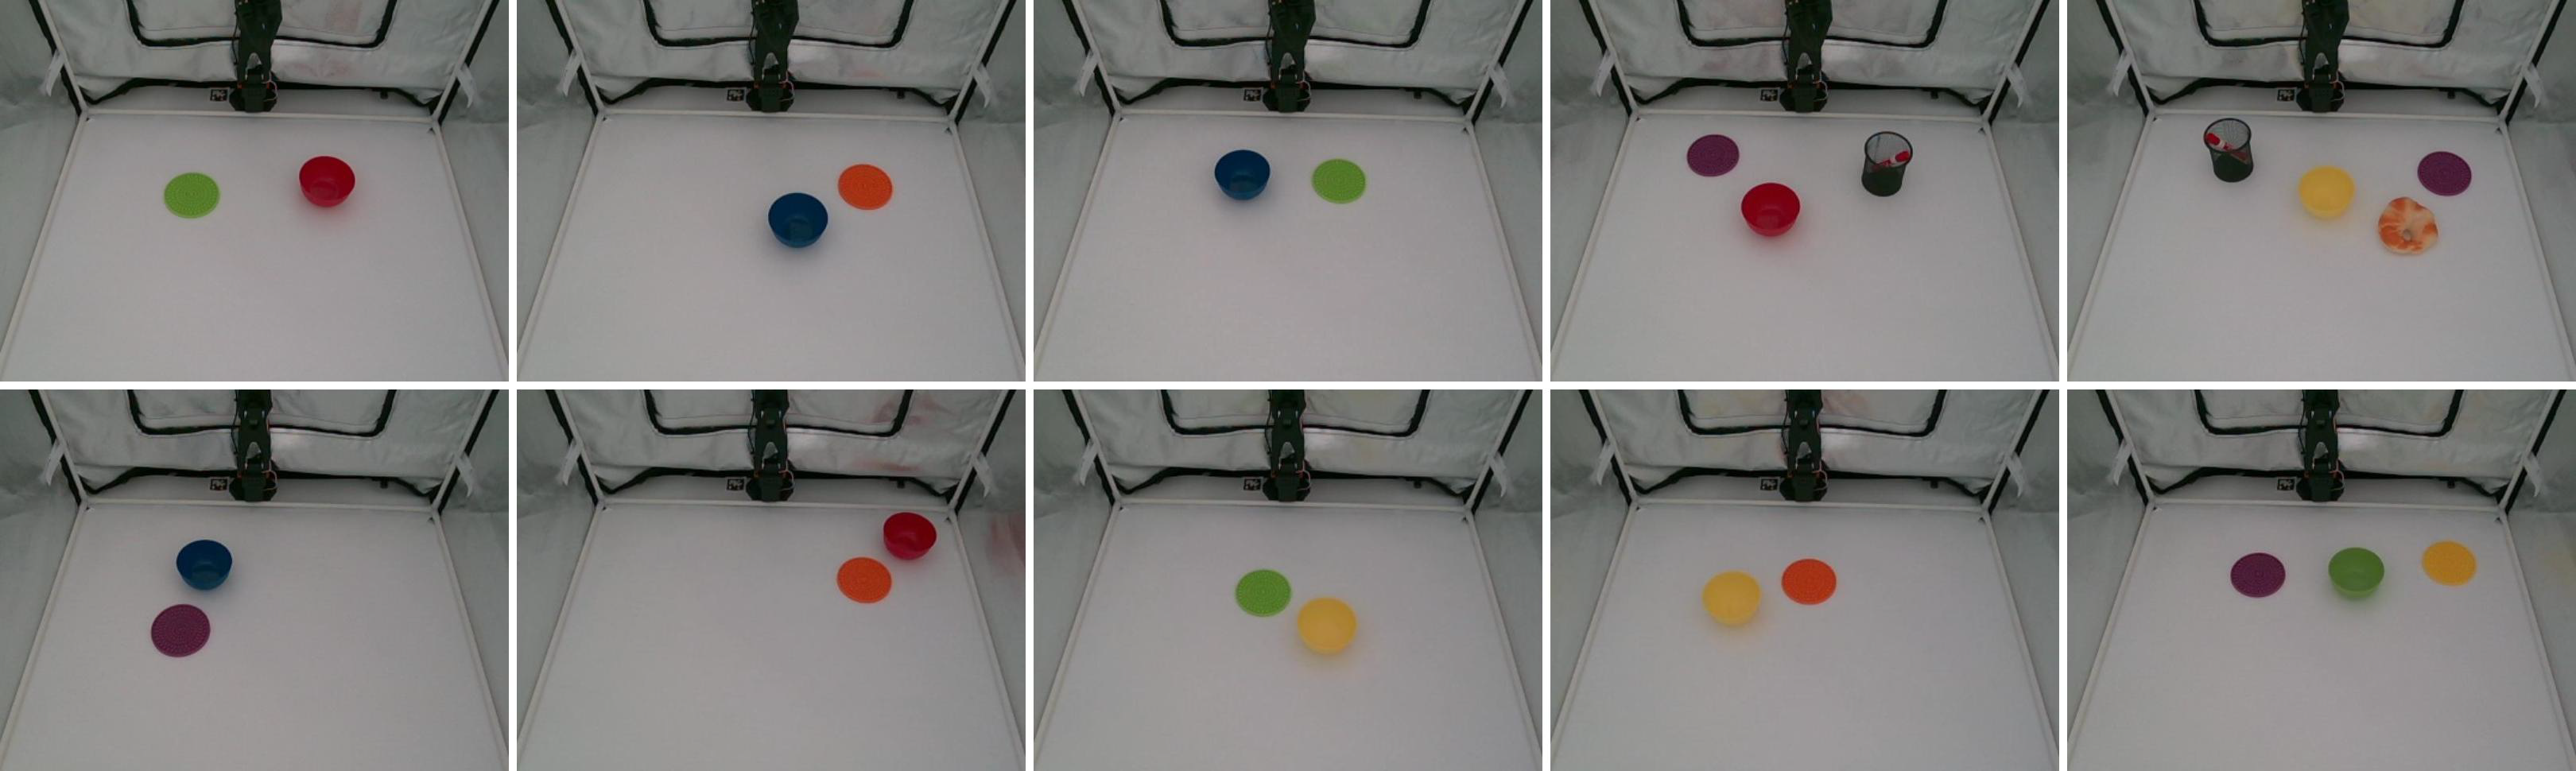
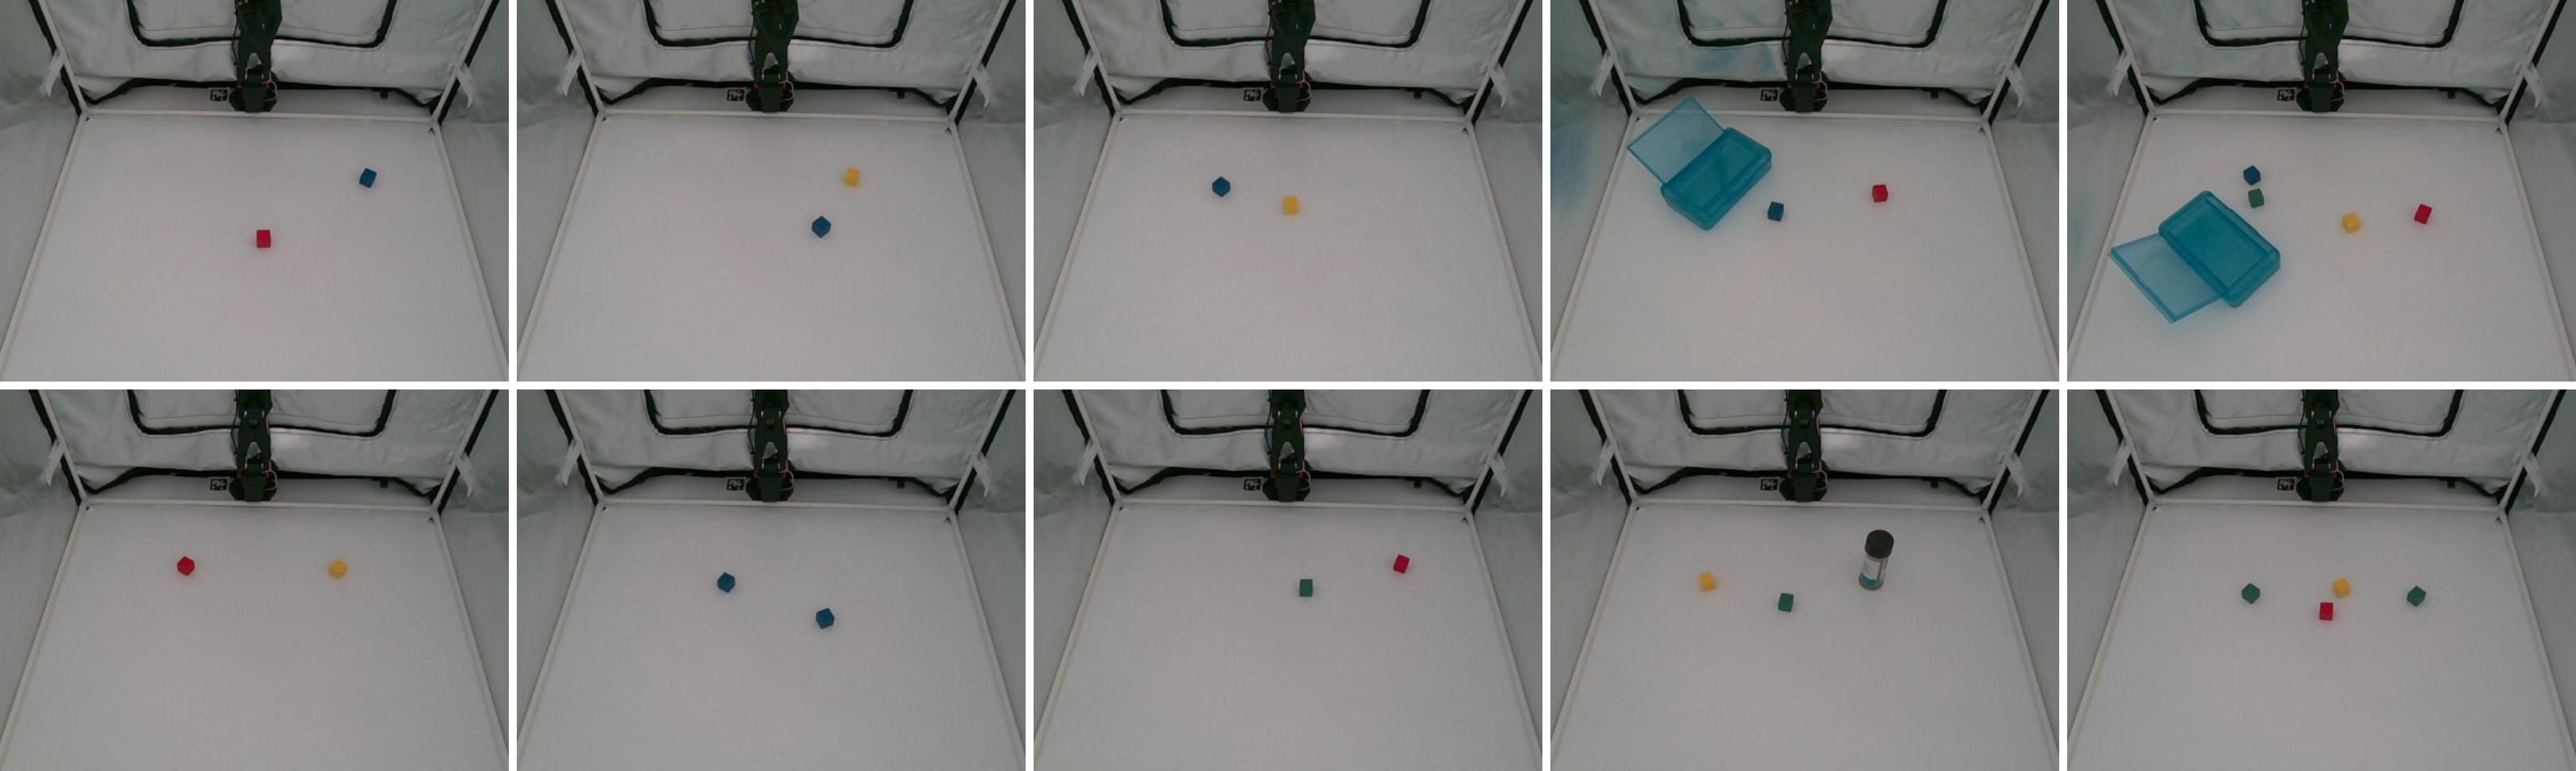
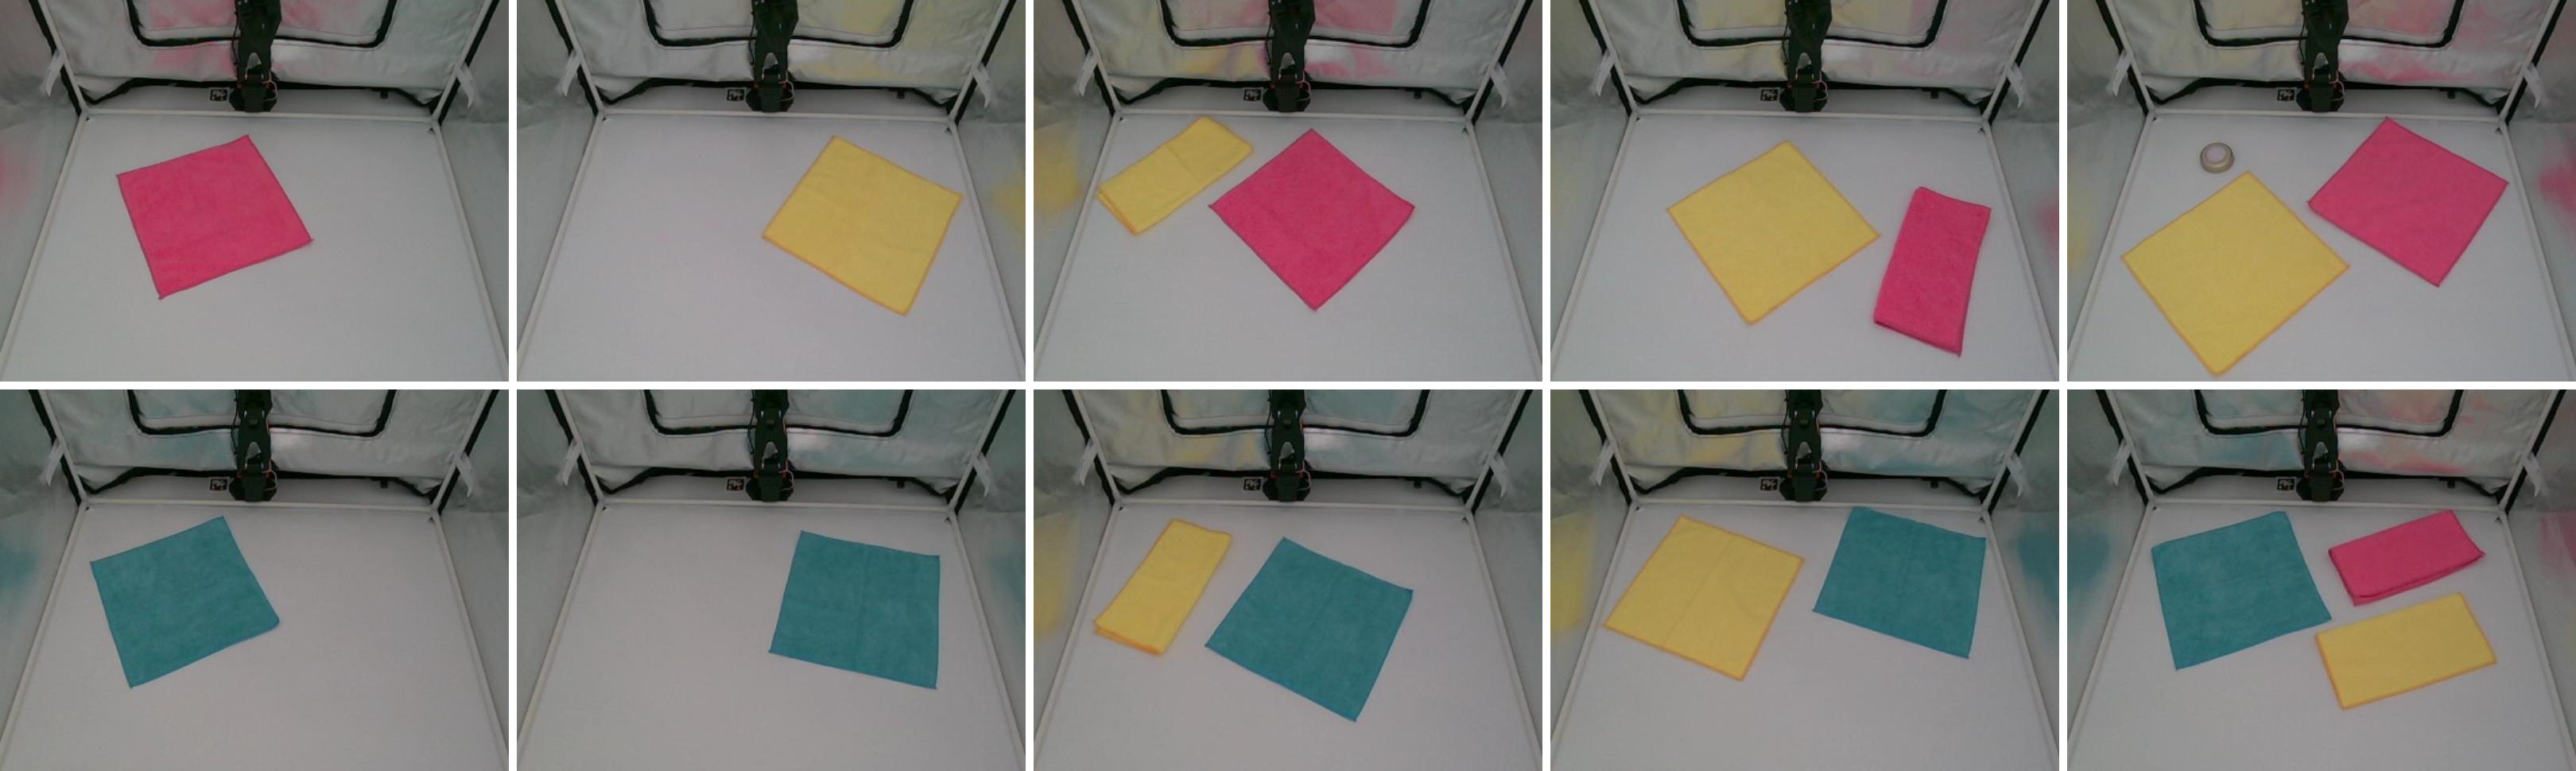
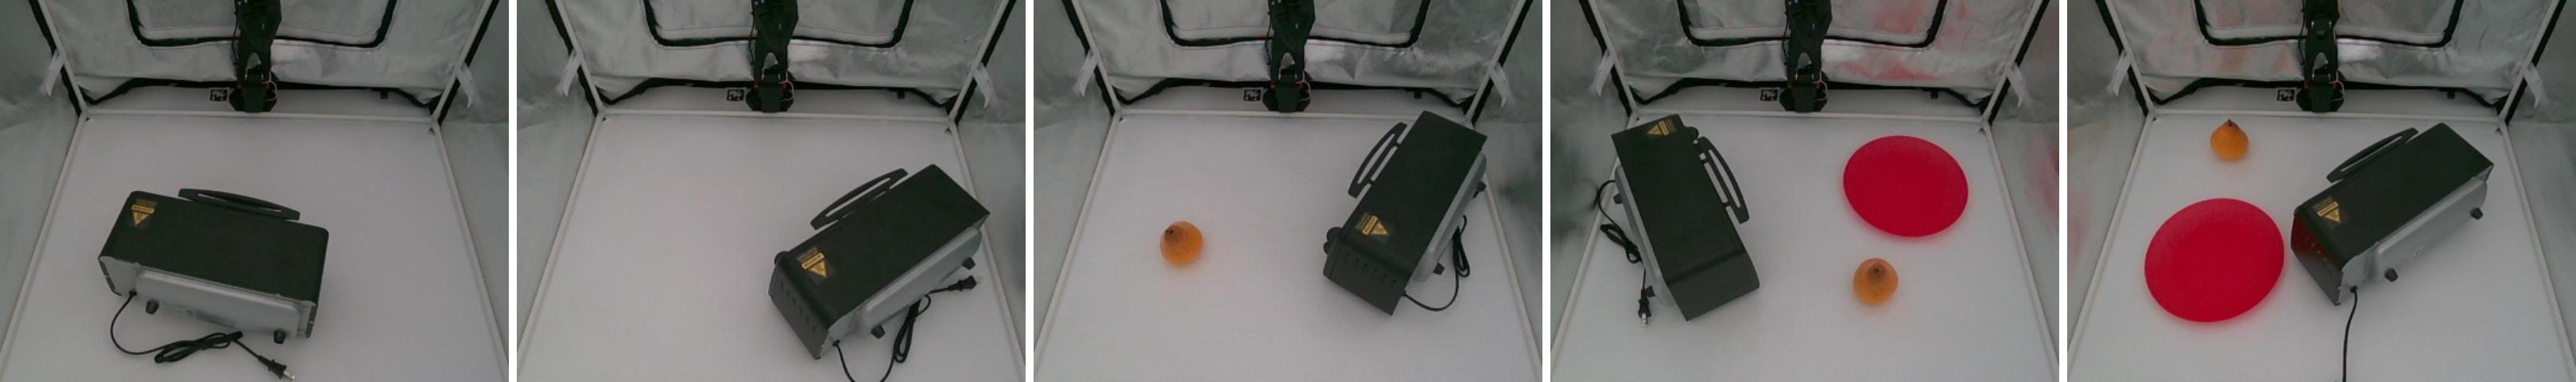
Match each test scene precisely.
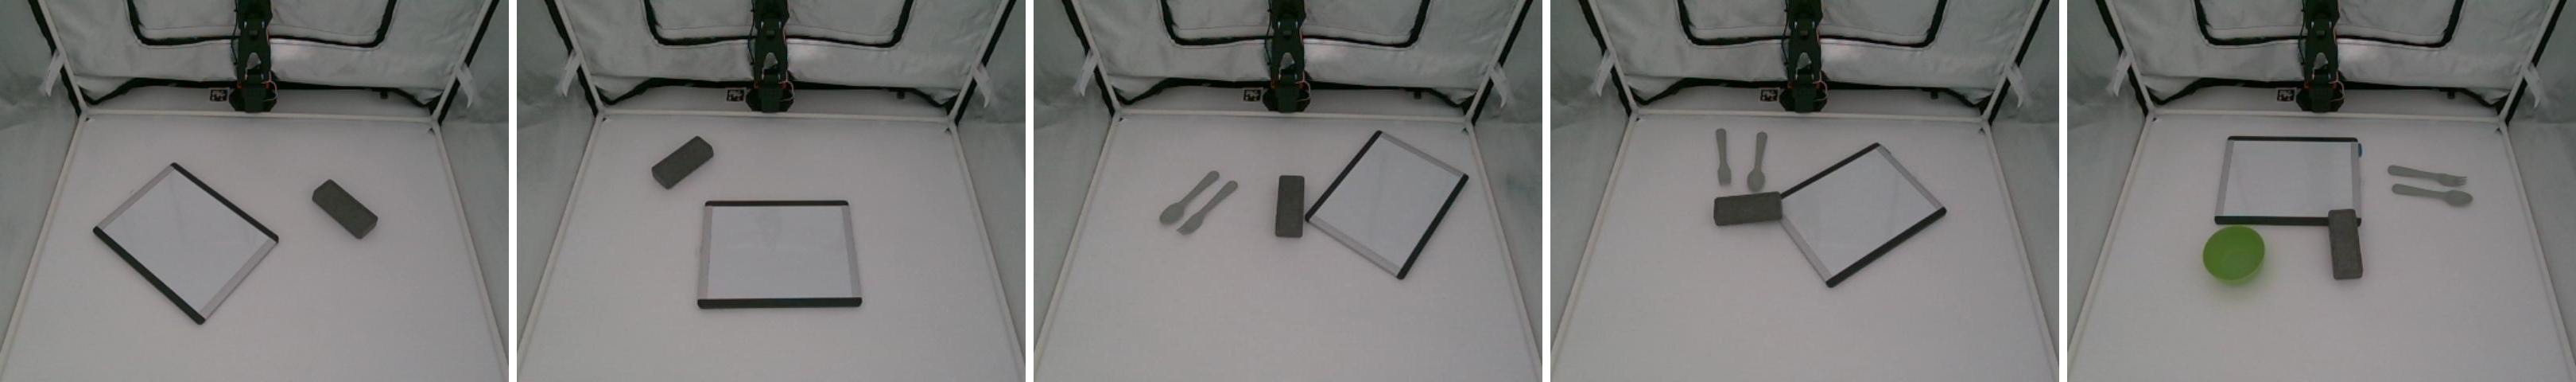
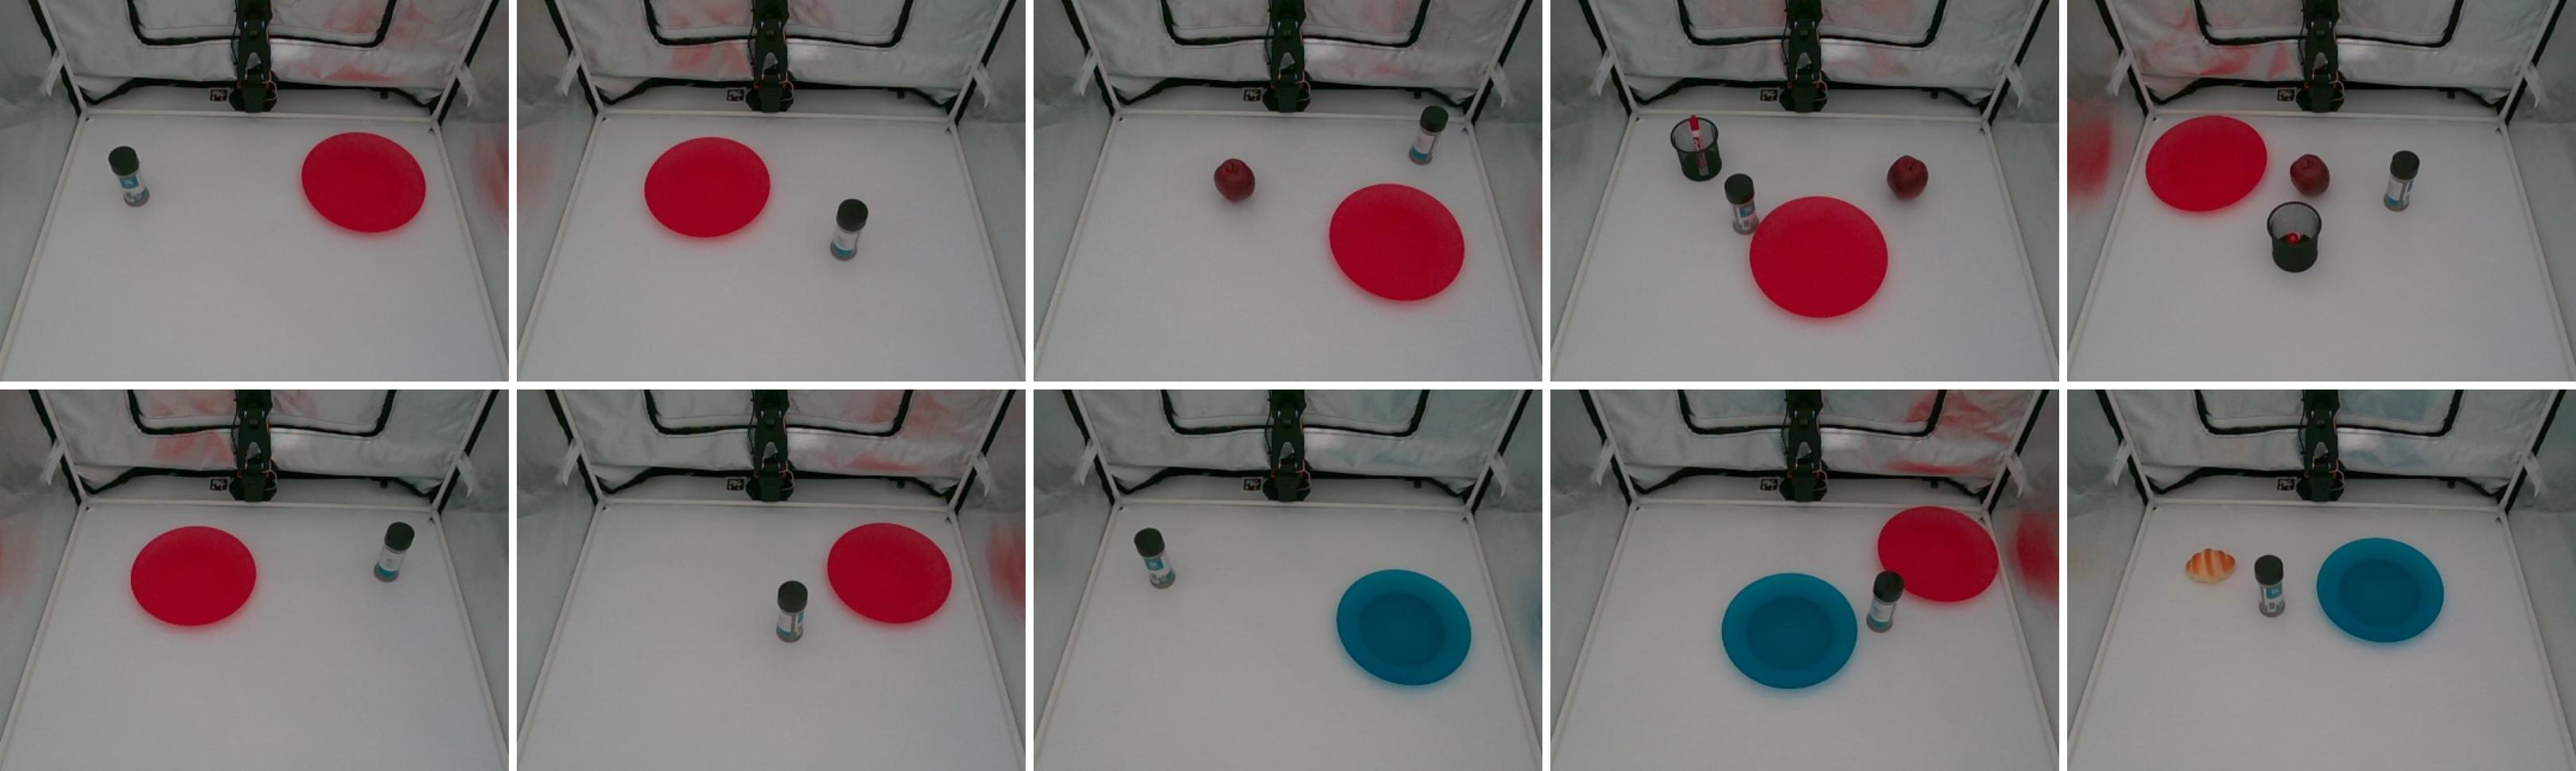
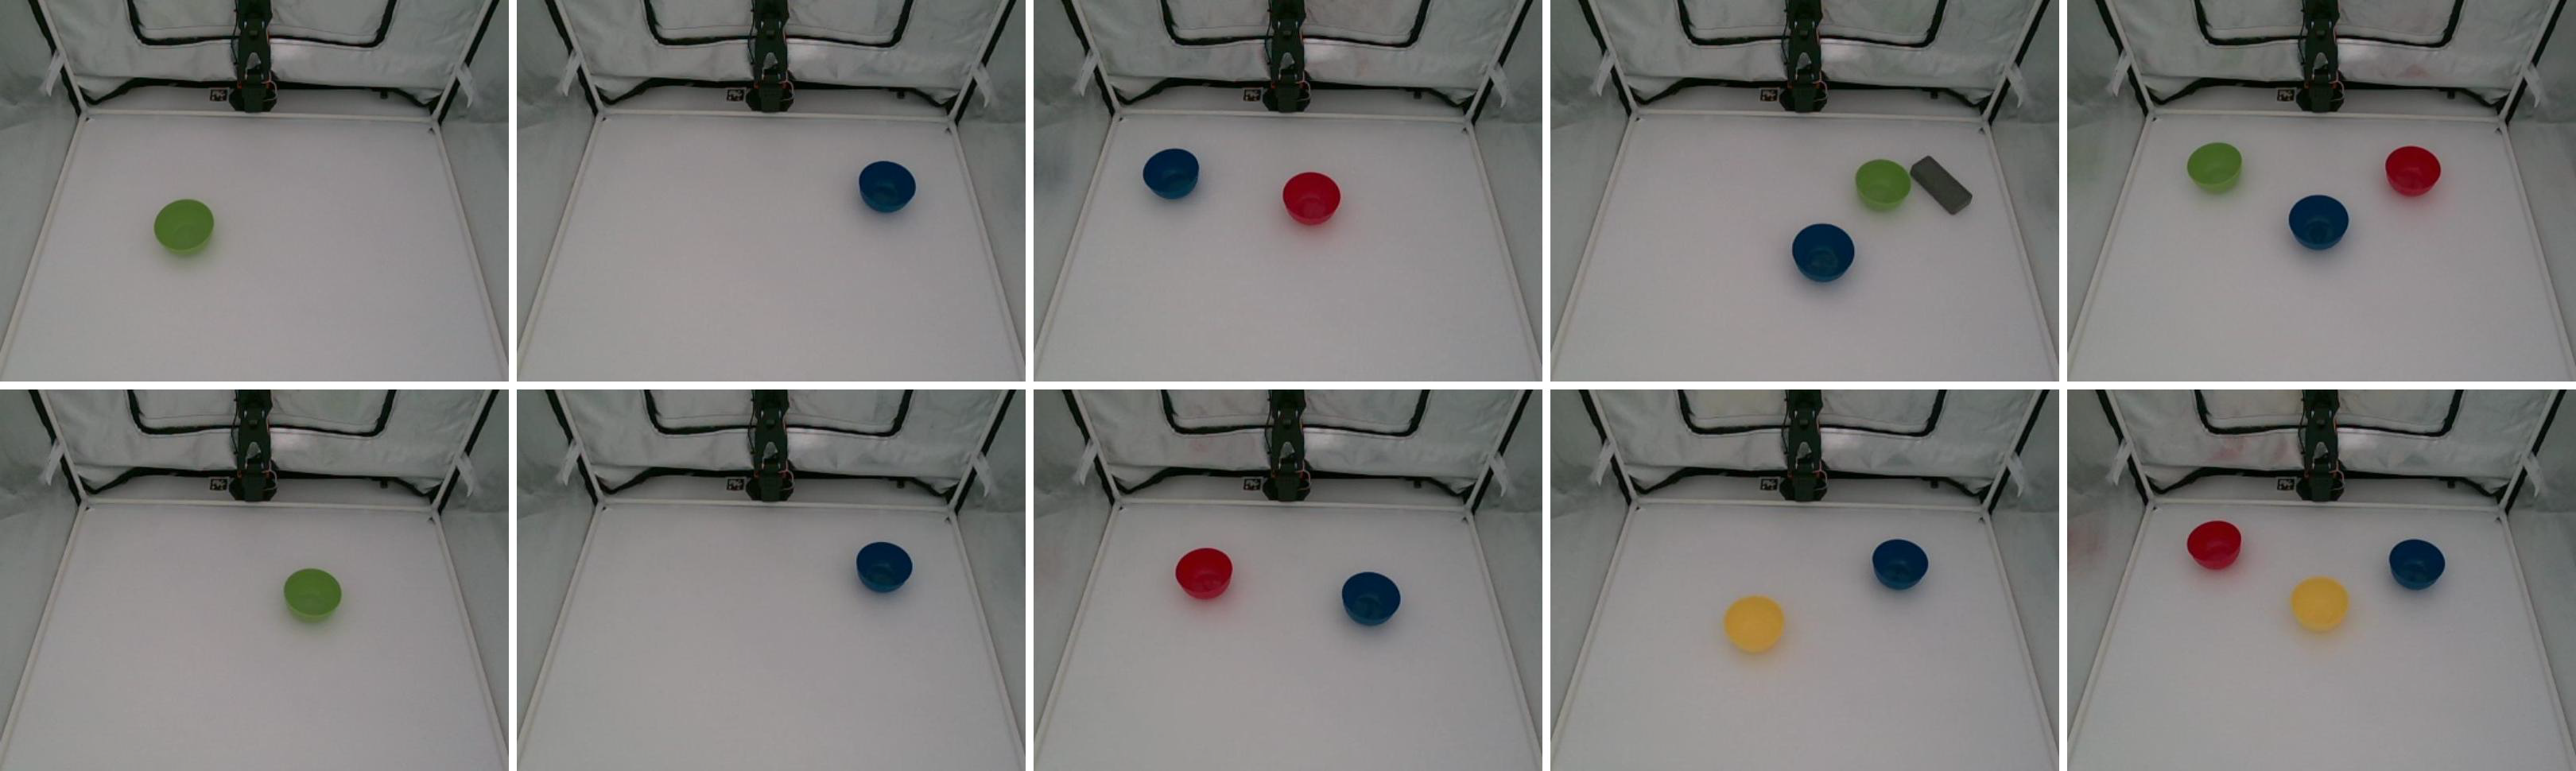
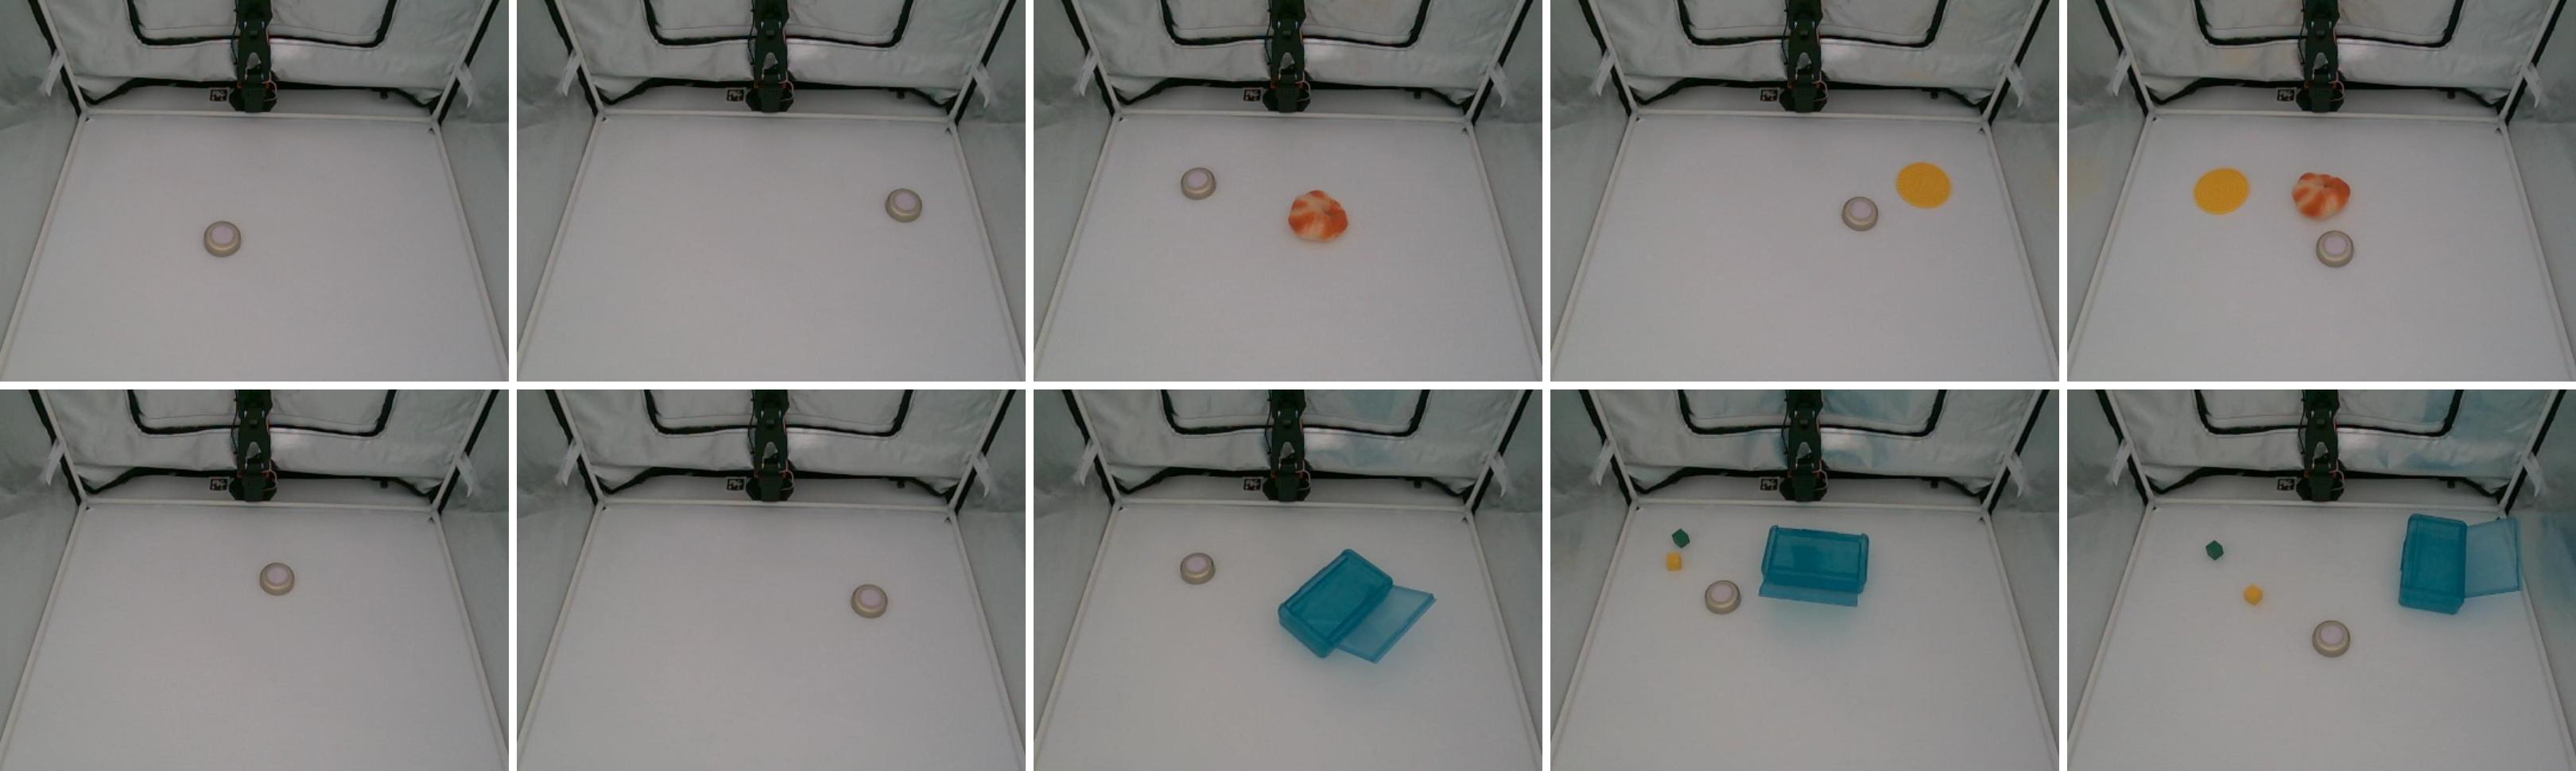
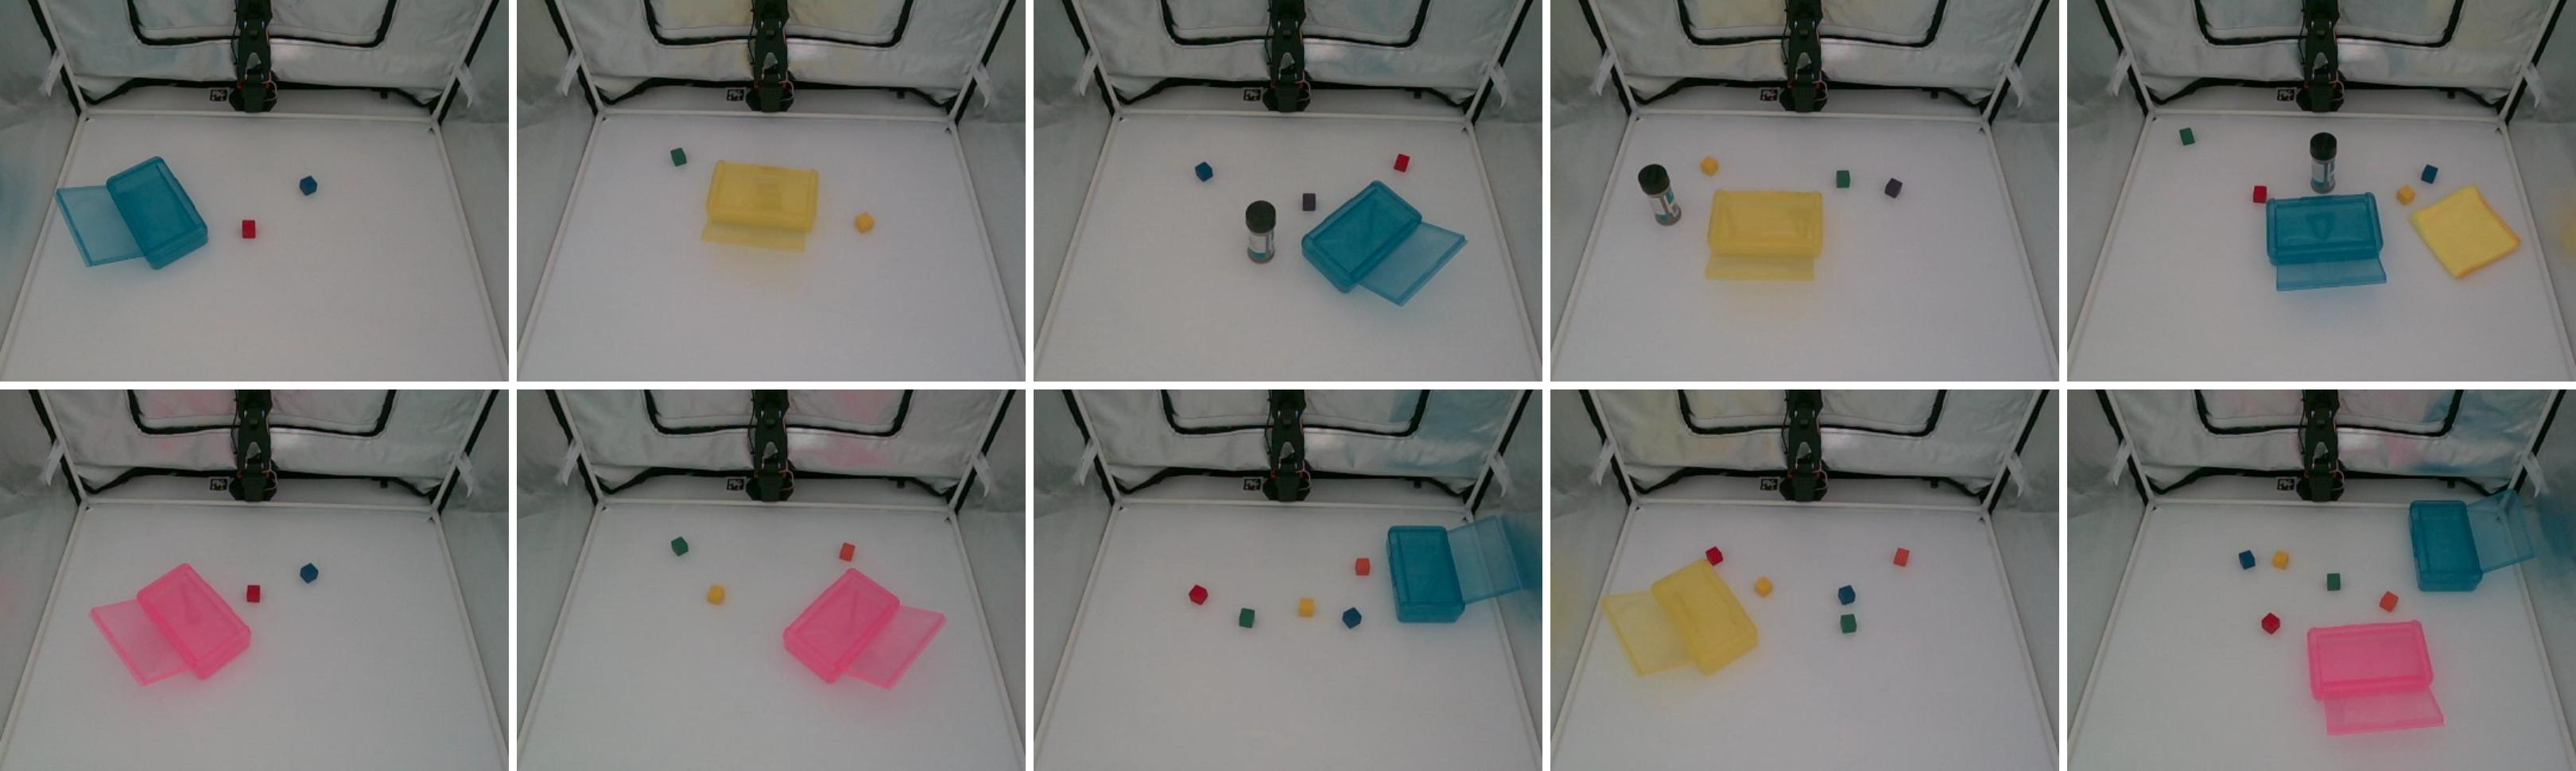
Use the corresponding reference image to reproduce the object positions and orientations before every evaluation rollout. This walkthrough demonstrates the placement process.
Ninety fixed reference scenes make physical evaluation repeatable. The first row of each image shows ID conditions and the second shows OOD conditions, except for tasks without an OOD variant.
08 / LEADERBOARD
Leaderboard
Verified results include compatible publicly released policies evaluated by RobotReplica, alongside submitted policies. Success rates use five rollouts per task; switch evaluation tracks, sort by any task, and use the video link to inspect every rollout for a method.
| Rank | Method | Video | |||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 1 | π₀.₅6 | 0.54 | 0.8 | 0.8 | 0.4 | 0.4 | 1 | 0.6 | 0.4 | 0.4 | 0.4 | 0.2 | ↗ |
| 2 | MolmoAct2-SO100_1017 | 0.46 | 1 | 0.8 | 0.4 | 0.4 | 0.6 | 0.4 | 0.6 | 0.2 | 0.2 | 0 | ↗ |
| 3 | GR00T1.78 | 0.36 | 0.8 | 0.8 | 0 | 0.2 | 1 | 0.2 | 0.2 | 0.2 | 0 | 0.2 | ↗ |
| 4 | π₀5 | 0.34 | 0.8 | 0.6 | 0 | 0 | 0.8 | 0.2 | 0.4 | 0.2 | 0.2 | 0.2 | ↗ |
| 5 | SmolVLA3 | 0.26 | 0.6 | 0.2 | 0.2 | 0 | 0.6 | 0.4 | 0.2 | 0 | 0.2 | 0.2 | ↗ |
| 6 | ACT1 | 0.18 | 0.4 | 0 | 0 | 0 | 0.4 | 0.4 | 0.2 | 0.2 | 0.2 | 0 | ↗ |
| 7 | DiT-D2 | 0.16 | 0.4 | 0 | 0 | 0.2 | 0.2 | 0.6 | 0.2 | 0 | 0 | 0 | ↗ |
| 8 | X-VLA4 | 0.14 | 0.4 | 0.2 | 0 | 0 | 0.6 | 0 | 0 | 0.2 | 0 | 0 | ↗ |
| 9 | DiT-F2 | 0.12 | 0.4 | 0 | 0 | 0 | 0.2 | 0.4 | 0.2 | 0 | 0 | 0 | ↗ |
Select Average or any task heading to rank methods. Use the arrow in the Video column to open all five rollout videos for every task.
TRAINING DETAILS
Training & Model Parameters
Implementation and training settings used for each evaluated policy.
| Parameter | ACT | DiT-D | DiT-F | SmolVLA | X-VLA | π₀ | π₀.₅ | MolmoAct2-SO100_101 | GR00T1.7 |
|---|---|---|---|---|---|---|---|---|---|
| Training type | From scratch | From scratch | From scratch | Fine-tuning | Fine-tuning | Fine-tuning | Fine-tuning | Fine-tuning | Fine-tuning |
| Dataset size | 500 demos | 500 demos | 500 demos | 500 demos | 500 demos | 500 demos | 500 demos | 500 demos | 500 demos |
| Batch size | 128 | 128 | 128 | 128 | 128 | 16 | 16 | 16 | 32 |
| Training steps | 40K | 40K | 40K | 40K | 40K | 40K | 40K | 40K | 40K |
| GPUs | 2 | 1 | 1 | 4 | 4 | 1 | 1 | 4 | 4 |
| GPU type | A6000 Ada | H200 | H200 | A6000 Ada | A6000 Ada | H200 | H200 | A6000 Ada | A6000 Ada |
| Action chunk size | 32 | 32 | 32 | 32 | 32 | 32 | 32 | 32 | 32 |
| Number of action steps | 32 | 24 | 24 | 32 | 32 | 32 | 32 | 32 | 32 |
| Vision encoder | Default | Default | Default | Default | Trainable | Frozen | Default | Default | Default |
| Implementation | LeRobot | LeRobot | LeRobot | LeRobot | LeRobot | LeRobot | LeRobot | LeRobot | LeRobot |
| Learning rate | Default | Default | Default | Default | Default | Default | Default | Default | Default |
References
- Zhao, Tony Z., Vikash Kumar, Sergey Levine, and Chelsea Finn. “Learning Fine-Grained Bimanual Manipulation with Low-Cost Hardware.” arXiv preprint arXiv:2304.13705, 2023.
- Jones, Bryson. “Dissecting and Open-Sourcing Multitask Diffusion Transformer Policy.” Blog post, 2026.
- Shukor, Mustafa, Dana Aubakirova, Francesco Capuano, Pepijn Kooijmans, Steven Palma, Adil Zouitine, Michel Aractingi, et al. “SmolVLA: A Vision-Language-Action Model for Affordable and Efficient Robotics.” arXiv preprint arXiv:2506.01844, 2025.
- Zheng, Jinliang, Jianxiong Li, Zhihao Wang, Dongxiu Liu, Xirui Kang, Yuchun Feng, Yinan Zheng, et al. “X-VLA: Soft-Prompted Transformer as Scalable Cross-Embodiment Vision-Language-Action Model.” arXiv preprint arXiv:2510.10274, 2025.
- Black, Kevin, Noah Brown, Danny Driess, Adnan Esmail, Michael Equi, Chelsea Finn, Niccolo Fusai, et al. “π₀: A Vision-Language-Action Flow Model for General Robot Control.” arXiv preprint arXiv:2410.24164, 2024.
- Physical Intelligence, Kevin Black, Noah Brown, James Darpinian, Karan Dhabalia, Danny Driess, Adnan Esmail, et al. “π₀.₅: A Vision-Language-Action Model with Open-World Generalization.” arXiv preprint arXiv:2504.16054, 2025.
- Fang, Haoquan, Jiafei Duan, Donovan Clay, Sam Wang, Shuo Liu, Weikai Huang, Xiang Fan, et al. “MolmoAct2: Action Reasoning Models for Real-world Deployment.” arXiv preprint arXiv:2605.02881, 2026.
- NVIDIA. “GR00T N1: An Open Foundation Model for Generalist Humanoid Robots.” arXiv preprint arXiv:2503.14734, 2025.
09 / CODE & RESOURCES
Run the benchmark
The public implementation includes training, calibration, scene references, and evaluation utilities.
View code on GitHub10 / CITATION
BibTeX
Please cite VLA-Replica if it helps your research.
@misc{huang2026vlareplicalowcostreproduciblebenchmark,
  title={VLA-REPLICA: A Low-Cost, Reproducible Benchmark for
    Real-World Evaluation of Vision-Language-Action Models},
  author={Alex S. Huang and Jiahui Zhang and Shiqing Tang and Yu Xiang},
  year={2026},
  eprint={2605.20774},
  archivePrefix={arXiv},
  primaryClass={cs.RO},
  url={https://arxiv.org/abs/2605.20774}
}
11 / CONTACT
Evaluate with RobotReplica
Submit your policy information through the RobotReplica evaluation form. The team will coordinate the hosted evaluation and leaderboard submission with you.
Request an evaluationACKNOWLEDGEMENTS
This work was supported in part by the National Science Foundation under Grant Nos. 2346528 and 2520553, the NVIDIA Academic Grant Program Award, and gift funding from XPeng.